
Why Big Small Prediction Hack Pages Fail
Search interest for big small prediction hack is easy to understand. People want a shortcut that removes uncertainty from quick rounds. The problem is not curiosity. The problem is that hack pages usually sell certainty in a format where each round resolves independently. That mismatch is why most hack pages collapse under even a basic reality check.
This article explains how those pages are built, what signals to question first, and how to protect your decision process if you still want to learn the round format. The goal is not to lecture readers. The goal is to make false confidence easier to spot before it costs money.
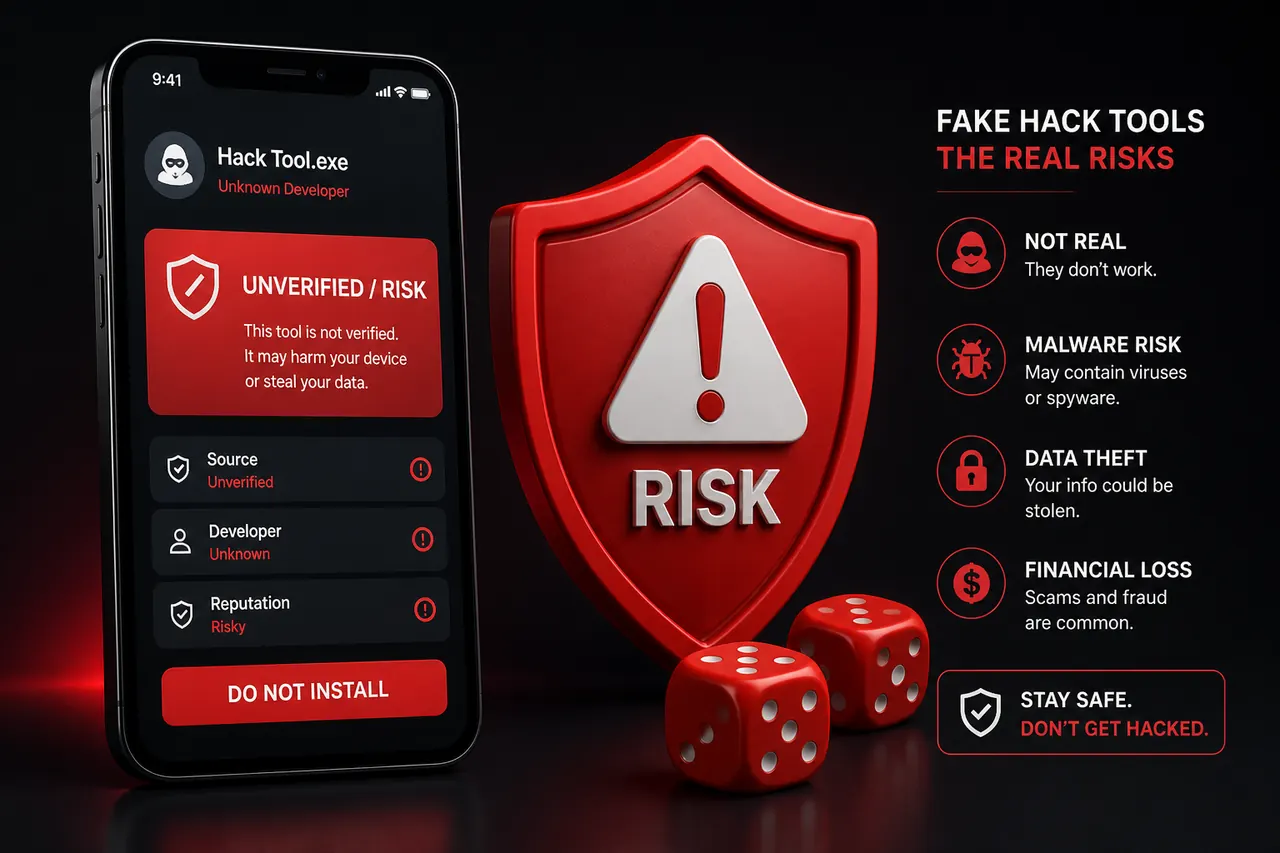
big small prediction guide
Why hack claims sound convincing at first
Hack pages use familiar persuasion patterns: "live proof," "AI analysis," "insider panel," and "limited-time access." These labels are emotionally strong because they imply private knowledge, not public probability. If someone feels late to the game, that urgency can sound like opportunity.
Most of these pages also copy real terms from the Big Small ecosystem: period IDs, history strips, and color labels. That gives the interface a technical look even when the core claim is still unproven. A screen can look advanced and still be fiction.
The key point is simple: technical vocabulary is not evidence. If a page cannot show a transparent method that survives independent checks, language alone should not earn trust.
big small prediction guide
The randomness gap hack pages cannot close
In WinGo-style Big Small flow, a result strip is a record of completed rounds. It is not a command for the next round. A history sequence can show patterns because random outputs naturally form streaks. Human eyes are wired to see those streaks as meaning something deep, even when they are statistically normal.
Hack pages exploit this gap. They replay history, highlight selected wins, and describe ordinary variance as "model accuracy." What they do not provide is a verifiable mechanism that guarantees forward prediction. Without that mechanism, "high success rate" is marketing language.
This is where many readers get trapped: a tool that describes past rounds clearly can still fail as a future predictor. Explanation and prediction are not the same job.
big small prediction guide
Common proof formats that mislead readers
A lot of hack content uses the same proof package: screenshots, short clips, and testimonial-style statements. Each item can feel persuasive in isolation, but none is reliable by default.
- Screenshot chains hide failed calls by deleting loss periods.
- Video clips can be trimmed to keep only winning segments.
- "User reports" often lack timestamps you can verify independently.
- Accuracy percentages are shown without method notes or sample rules.
- Paid channel invites appear right after emotional "proof" blocks.
The structure matters. When evidence is always paired with urgency and payment pressure, you are no longer reading neutral analysis. You are inside a conversion funnel.
big small prediction guide
How to run a quick credibility check
Before trusting any hack claim, pause and run a short audit:
- BAsk what exact method creates each next-round call.
- SCheck whether failed predictions are visible, not hidden.
- BLook for independently verifiable timestamps and period IDs.
- SSeparate educational history reading from "guaranteed next result."
- BRefuse any page that demands payment before transparent testing.
- SStep away if the language promises certainty or fixed outcomes.
This checklist does not guarantee you will never make a bad decision. It does reduce exposure to obvious manipulation patterns. That alone is a meaningful improvement.
big small prediction guide
Why "AI bot" wording does not solve the problem
Adding AI branding does not change probability. A bot can process numbers quickly, classify streaks, and produce neat dashboards. None of that creates guaranteed control over independent random rounds. Speed is not certainty.
Many "AI hack" pages rely on ambiguity. They never define how the model is trained, what data scope is used, or how overfitting is handled. They simply replace old "secret trick" language with modern "machine intelligence" wording. The persuasion style changes, but the evidence gap remains.
If a claim says the system "almost never loses," ask for full-session logs with clear fail counts. Most pages cannot provide them, because the promise is designed for emotional impact, not scientific review.
big small prediction guide
A better use of tools: practice, not promises
Tools are not useless. They become useful when used as practice support. A clean history panel can help you learn the interface. A timer display can improve pacing discipline. Session notes can reduce impulsive decisions.
Where trouble starts is role confusion. If a learning tool is sold as a guaranteed predictor, the reader inherits unrealistic expectations. That tension often leads to bigger stakes and lower control.
The healthier framing is this: use tools to structure observation and self-control, not to replace uncertainty with fantasy. That framing keeps the learning benefit while removing the most dangerous promise.
big small prediction guide
What to remember before your next session
Hack pages fail because they promise certainty where uncertainty is built into the format. Technical design, social proof, and AI language can make a claim look modern, but appearance is not validation. If the proof is selective, the model is vague, and payment pressure is high, walk away.
Treat Big Small practice as education, not a shortcut to guaranteed outcomes. Keep limits visible, use demo sessions first, and assume each round is independent from the previous strip.
FAQ
Are all big small prediction hack pages scams?
Not every page is identical, but most use weak evidence patterns and certainty-based language. The safest approach is to require transparent, testable methods before trusting any claim.
Why do streak screenshots look so convincing?
Because random data naturally creates short streaks, and curated screenshots can hide losses. Visual confidence is easy to manufacture without proving forward accuracy.
Can an AI bot accurately predict every round?
No credible system can guarantee every round in an independent random format. AI tools may assist with organization, but certainty claims are a major red flag.
Is it okay to use tools at all?
Yes, if the tool is used for practice and session structure rather than guaranteed outcomes. Keep expectations realistic and avoid payment funnels tied to certainty language.
What is the safest first step if I am unsure?
Use demo mode, cap your session length, and apply a credibility checklist before believing any hack claim. If the page uses urgency and guarantees, exit immediately.
By Meera Iyer - Prediction Myths Editor